Video 29 of 53 · 3:24 · Applications, benchmarking and evidence
Guards for a fair exact comparison
In this video
Caption transcript
Show transcript
This overview explains how correctness checks, execution order, clustered sampling, and uncertainty protect a benchmark.
Precise timing cannot repair an incorrect output, a weak comparator, or an invalid dependence model.
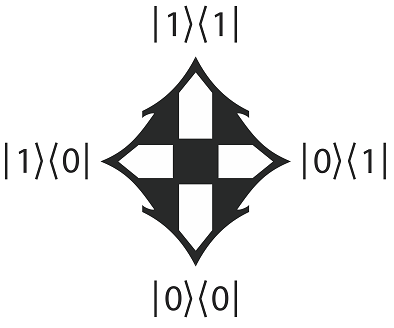
Suppose the required and vector is zero zero zero one, but a fast candidate produces zero
zero one one.
At input one zero, the candidate returns one where the rule requires zero.
That mismatch is enough to reject its exactness claim.
The invalid output cannot be celebrated as a faster exact solution.
Keep its failed record in the audit trail, but separate it from valid timing comparisons.
A timing improvement does not compensate for changing the answer.
A matching output hash can confirm that two stored byte sequences match.
It does not prove that the bytes represent the right variable order or the right problem.
Check the contract and compare with an independent exact reference.
Correctness, execution order, dependent sampling and uncertainty are separate problems.
A precise timer does not solve them all.
First compare each arm's exact output with the frozen reference.
A mismatched output is not an eligible speed result.
Next counterbalance arm order so one arm does not always inherit the warm position.
Group repeated observations by the formula or circuit that generated them.
Finally construct an interval with that cluster as the resampling unit.
Ten repeated runs of one formula are still one formula identity.
A digest binds an output to an identity but is not an independent semantic oracle.
A small-domain scalar check supplies independent correctness evidence here.
A within-run clustered interval does not establish between-machine variation.
Record invalid rows and refusals instead of dropping them after seeing timings.
If the first method always runs cold and the second always runs warm, order
can bias the comparison.
A protocol should declare how order is controlled or varied and what state is reset.
The correct design depends on the intended cold or resident task.
Repeated runs of the same formula are useful for timing variability, but they remain
clustered around one input identity.
An analysis that treats them as ten unrelated formulas exaggerates the range of evidence.
Do not silently remove failed or refused rows and then describe the surviving timings as
if every case succeeded.
The audit should show the original population, the reasons for exclusions, and the precise
set supporting the reported result.
Check exact outputs and freeze the comparison protocol.
Keep dependent repeats within their formula clusters and report refusals and invalid rows.